研究

52

頂會論文

10

2026 年論文

30+

開源項目

3 萬+

GitHub Star

同步

論文 · 權重 · 代碼

來自社區

UniRig 爲每個角色省下了一週的權重繪製。那套舊工具,我們再也沒打開過。

Kai Brennan,技術總監 — Longhand
每年用一個開源版本綁定約兩百個角色

02論文

每篇論文,連同代碼與權重。

四年五十二篇論文。權重、代碼與插件,均在論文發佈當天開放。

SIGGRAPH 2026

July 19, 2026

PixTex: Consistent 3D Texturing via Pixel-Space Multi-View Diffusion

Yuqing Zhang, Yan-Pei Cao, Hao Xu, Yiqian Wu, Sirui Lin, Yuqing Wang, Ding Liang, Yuan-Chen Guo, Xiaogang Jin

PixTex performs multi-view diffusion directly in pixel space to generate high-quality, globally consistent textures for 3D assets.

2026
SIGGRAPH 2026

July 15, 2026

Nexus: Native Mesh Generation with Diffusion

Hanxiao Wang, Ying-Tian Liu, Yuan-Chen Guo, Qi-Yuan Feng, Zi-Xin Zou, Ding Liang, Biao Zhang, Yan-Pei Cao

Nexus generates native triangle meshes with diffusion by decoupling vertex generation and topology modeling, avoiding the inefficiency of autoregressive mesh serialization.

2026
ACM Transactions on Graphics

June 11, 2026

Grow3D: Hierarchical Next-Scale Octree Prediction for Fast and High-Fidelity 3D Shape Generation

Qi-Yuan Feng, Zi-Xin Zou, Haoxiang Chen, Yuanchen Guo, Yan-Pei Cao, Tai-Jiang Mu, Shi-Min Hu

Grow3D is an autoregressive 3D shape generation framework that predicts hierarchical octree structures in a coarse-to-fine manner, enabling fast and high-fidelity 3D generation.

2026
SIGGRAPH 2026

June 10, 2026

TopoCap: Learning Topology-Agnostic Motion Priors for Monocular Video-to-Animation

Cheng-Feng Pu, Jia-Peng Zhang, Meng-Hao Guo, Yan-Pei Cao, Shi-Min Hu

TopoCap extracts motion from monocular videos and retargets it to 3D characters with arbitrary skeletal topologies, enabling topology-agnostic video-to-animation.

2026
CVPR 2026

June 5, 2026

Beyond Reassembly: Fractured Object Recovery with Missing Parts

Qun-Ce Xu, Jiahui Li, Yan-Pei Cao, Weihao Cheng, Tai-Jiang Mu, Ying Shan, Chuan Li, Da Chen, Yong-Liang Yang, Shi-Min Hu

This work addresses fractured object recovery by not only reassembling observed fragments, but also predicting missing parts to reconstruct the complete object shape.

2026
SIGGRAPH 2026

May 8, 2026

Generative 3D Gaussians with Learned Density Control

Runjie Yan, Yan-Pei Cao, Peng Wang, Ding Liang, Yuan-Chen Guo

TripoSplat introduces Density-Sampled Gaussians (DeG) for fully adaptive, grid-free 3D generation. We achieve differentiable densification by parameterizing primitive centers as samples from a learnable spatial density, optimized directly via a novel render-loss gradient. To model these unstructured sets, our VecSeq diffusion framework resolves permutation ambiguity by anchoring latents to a deterministic 3D Sobol sequence. TripoSplat achieves state-of-the-art single-image-to-3D generation while uniquely enabling variable-resolution decoding from a single compact latent code.

2026
SIGGRAPH 2026

April 9, 2026

AniGen: Unified S³ Fields for Animatable 3D Asset Generation

Yi-Hua Huang, Zi-Xin Zou, Yuting He, Chirui Chang, Cheng-Feng Pu, Ziyi Yang, Yuan-Chen Guo, Yan-Pei Cao, Xiaojuan Qi

AniGen overcomes the brittleness of sequential "generate-then-rig" pipelines by directly generating fully animatable 3D assets from a single image. We achieve this by unifying shape, skeleton, and skinning weights into a shared continuous spatial representation: S³ Fields. To model rigs of arbitrary complexity, we introduce a joint-count agnostic Dual Skin Field, paired with a confidence-decaying skeleton field that explicitly resolves topological ambiguities at kinematic boundaries. By generating these compressed fields via a two-stage structured latent flow-matching architecture, AniGen guarantees intrinsic structural consistency between geometry and articulation. The result is a robust, end-to-end foundation for generating production-ready, instantly animatable characters and objects across diverse categories.

2026
CVPR 2026

March 18, 2026

Stereo World Model: Camera-Guided Stereo Video Generation

Yang-Tian Sun, Zehuan Huang, Yifan Niu, Lin Ma, Yan-Pei Cao, Yuewen Ma, Xiaojuan Qi

StereoWorld is a camera-guided stereo video generation model that jointly learns appearance and binocular geometry, enabling consistent stereo video synthesis for VR and embodied AI applications.

2026
CVPR 2026 · Highlight

March 2, 2026

FACE: A Face-based Autoregressive Representation for High-Fidelity and Efficient Mesh Generation

Hanxiao Wang, Yuan-Chen Guo, Ying-Tian Liu, Zi-Xin Zou, Biao Zhang, Weize Quan, Ding Liang, Yan-Pei Cao, Dong-Ming Yan

Autoregressive mesh generation is traditionally bottlenecked by the quadratic compute cost of modeling flattened vertex coordinate sequences. FACE fundamentally resolves this by elevating generation to a higher semantic tier. Through a novel “one-face-one-token” strategy, we encapsulate entire triangle faces into single unified tokens, slashing sequence lengths by a factor of nine. This architectural elegance yields an unprecedented compression ratio of 0.11, doubling the efficiency of prior state-of-the-art without relying on brittle, lossy traversal heuristics. By coupling this highly efficient Autoregressive Autoencoder (ARAE) with latent diffusion, FACE provides a robust, scalable, and compute-efficient foundation for high-fidelity direct mesh generation.

2026
Feb 2026

February 4, 2026

SkinTokens: A Learned Compact Representation for Unified Autoregressive Rigging

Jia-Peng Zhang, Cheng-Feng Pu, Meng-Hao Guo, Yan-Pei Cao, Shi-Min Hu

Current auto-rigging methods fail to scale because they treat skinning as a brittle, high-dimensional regression task decoupled from skeleton generation. SkinTokens solves this by compressing sparse skinning matrices into discrete token sequences. This enables TokenRig, an autoregressive framework that jointly synthesizes skeletal topology and surface deformations as a single coherent sequence. Post-trained via reinforcement learning (GRPO) with explicit geometric rewards, TokenRig generalizes robustly to complex, in-the-wild assets. By seamlessly unifying skeleton and skin prediction, the framework achieves up to a 133% improvement in skinning accuracy, establishing a scalable, end-to-end foundation for animation-ready 3D content.

2026
SIGGRAPH Asia 2025

December 14, 2025

LegoACE: Autoregressive Construction Engine for Expressive LEGO® Assemblies

Hao Xu, Yuqing Zhang, Yiqian Wu, Xinyang Zheng, Yutao Liu, Xiangjun Tang, Yunhan Yang, Ding Liang, Yingtian Liu, Yuanchen Guo, Yanpei Cao, Xiaogang Jin

Built on native brick tokenization and backed by our 55,000-model LegoVerse dataset, LegoACE is an autoregressive engine that generates expressive LEGO assemblies from text or normal maps.

2025
CVPR 2026

December 8, 2025

Unified Camera Positional Encoding for Controlled Video Generation

Cheng Zhang, Boying Li, Meng Wei, Yan-Pei Cao, Camilo Cruz Gambardella, Dinh Phung, Jianfei Cai

UCPE is a unified camera positional encoding that captures pose, intrinsics, and lens distortion in one formulation, achieving state-of-the-art camera controllability in video diffusion while adding under 1% trainable parameters.

2025
CVPR 2026 · Highlight

December 4, 2025

LaFiTe: A Generative Latent Field for 3D Native Texturing

Chia-Hao Chen, Zi-Xin Zou, Yan-Pei Cao, Ze Yuan, Guan Luo, Xiaojuan Qi, Ding Liang, Song-Hai Zhang, Yuan-Chen Guo

LaFiTe generates seamless textures directly on 3D surfaces through a sparse latent color field, exceeding prior reconstruction quality by over 10 dB PSNR—without any UV mapping.

2025
SIGGRAPH Asia 2025

November 25, 2025

ShapeGen: Towards High-Quality 3D Shape Synthesis

Yangguang Li, Xianglong He, Zi-Xin Zou, Zexiang Liu, Wanli Ouyang, Ding Liang, Yan-Pei Cao

ShapeGen is a scalable 3D shape synthesis framework that improves geometry quality and structural consistency via enhanced 3D representations, higher-resolution supervision, and linear transformer architectures.

2025
SIGGRAPH 2025

August 19, 2025

Sketch3DVE: Sketch-based 3D-Aware Scene Video Editing

Feng-Lin Liu, Shi-Yang Li, Yan-Pei Cao, Hongbo Fu, Lin Gao

Sketch3DVE is a sketch-based 3D-aware video editing framework, supporting precise structural manipulation of scenes under large viewpoint changes while preserving multi-view consistency and realistic video generation.

2025
CVPR 2026

August 19, 2025

GeoSAM2: Unleashing the Power of SAM2 for 3D Part Segmentation

Ken Deng, Yunhan Yang, Jingxiang Sun, Xihui Liu, Yebin Liu, Ding Liang, Yan-Pei Cao

Recasting 3D part segmentation as prompt-controllable multi-view 2D mask prediction atop a SAM2 backbone, GeoSAM2 reaches state-of-the-art interactive part segmentation without text input or per-shape training.

2025
SIGGRAPH Asia 2025

July 8, 2025

OmniPart: Part-Aware 3D Generation with Semantic Decoupling and Structural Cohesion

Yunhan Yang, Yufan Zhou, Yuan-Chen Guo, Zi-Xin Zou, Yukun Huang, Ying-Tian Liu, Hao Xu, Ding Liang, Yan-Pei Cao, Xihui Liu

OmniPart introduces a part-aware 3D generation framework that produces editable and structurally coherent 3D assets through controllable part decomposition and joint part synthesis.

2025
SIGGRAPH Asia 2025

July 5, 2025

SeqTex: Generate Mesh Textures in Video Sequence

Ze Yuan, Xin Yu, Yangtian Sun, Yuan-Chen Guo, Yan-Pei Cao, Ding Liang, Xiaojuan Qi

SeqTex reformulates 3D texture generation as a sequence modeling task, directly synthesizing high-fidelity UV texture maps from pretrained video diffusion priors for consistent and realistic mesh texturing. (arxiv.org)

2025
SIGGRAPH Asia 2025

June 24, 2025

AnimaX: Animating the Inanimate in 3D with Joint Video-Pose Diffusion Models

Zehuan Huang, Haoran Feng, Yangtian Sun, Yuanchen Guo, Yanpei Cao, Lu Sheng

AnimaX presents a feed-forward framework for animating articulated 3D assets by leveraging video diffusion motion priors to generate coherent motions across arbitrary skeleton structures.

2025
SIGGRAPH Asia 2025

June 20, 2025

Assembler: Scalable 3D Part Assembly via Anchor Point Diffusion

Wang Zhao, Yan-Pei Cao, Jiale Xu, Yuejiang Dong, Ying Shan

Assembler frames 3D part assembly as a diffusion-based generative task, enabling scalable reconstruction of complex objects from input parts and reference images through sparse anchor point representations. (arXiv)

2025
SIGGRAPH 2025

April 16, 2025

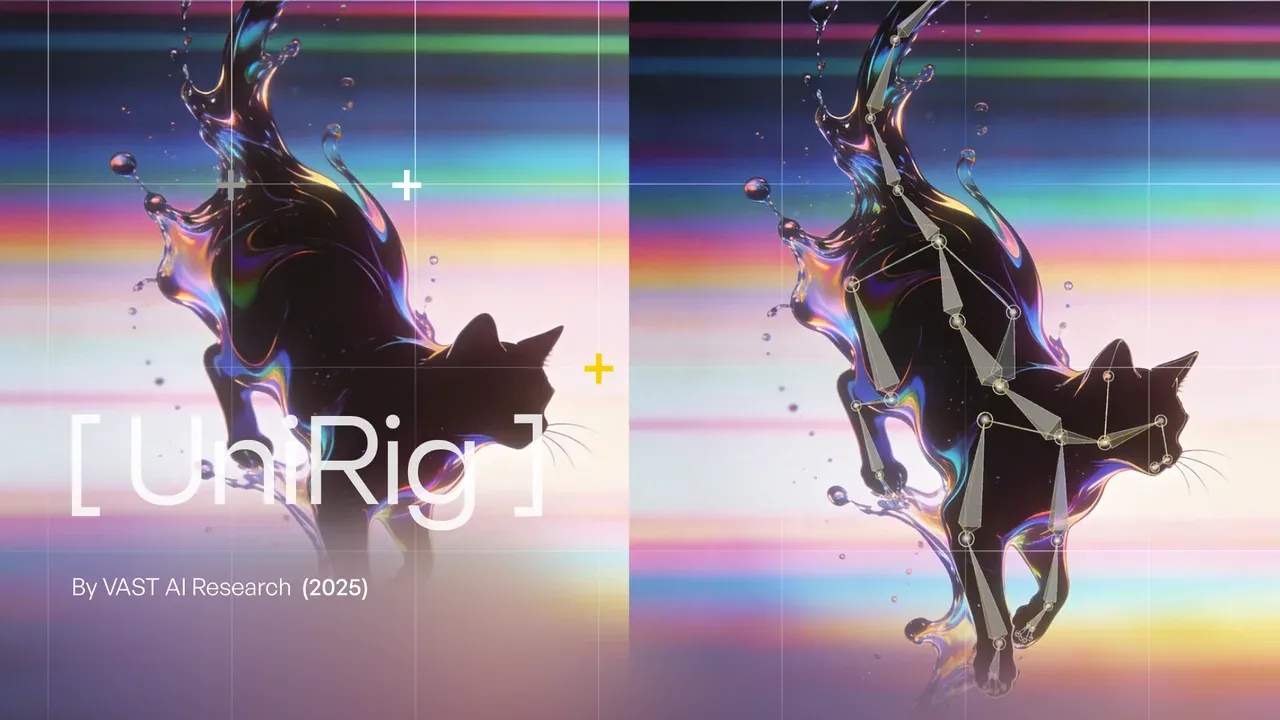
One Model to Rig Them All: Diverse Skeleton Rigging with UniRig

Jia-Peng Zhang, Cheng-Feng Pu, Meng-Hao Guo, Yan-Pei Cao, Shi-Min Hu

UniRig develops a unified autoregressive rigging framework that automatically generates high-quality skeletons and skinning weights for diverse 3D assets with complex topologies and categories.

2025
ICLR 2026

April 10, 2025

HoloPart: Generative 3D Part Amodal Segmentation

Yunhan Yang, Yuan-Chen Guo, Yukun Huang, Zi-Xin Zou, Zhipeng Yu, Yangguang Li, Yan-Pei Cao, Xihui Liu

HoloPart tackles 3D part amodal segmentation through a diffusion-based framework that reconstructs complete semantic parts from incomplete or occluded 3D geometry while preserving global shape consistency.

2025
ICCV 2025

March 28, 2025

GCRayDiffusion: Pose-Free Surface Reconstruction via Geometric Consistent Ray Diffusion

Li-Heng Chen, Zi-Xin Zou, Chang Liu, Tianjiao Jing, Yan-Pei Cao, Shi-Sheng Huang, Hongbo Fu, Hua Huang

GCRayDiffusion enhances pose-free 3D surface reconstruction by integrating geometrically consistent ray diffusion into triplane-based SDF learning, enabling accurate camera pose estimation and robust reconstruction from sparse-view inputs.

2025
ICCV 2025

March 27, 2025

SparseFlex: High-Resolution and Arbitrary-Topology 3D Shape Modeling

Xianglong He, Zi-Xin Zou, Chia-Hao Chen, Yuan-Chen Guo, Ding Liang, Chun Yuan, Wanli Ouyang, Yan-Pei Cao, Yangguang Li

Built on the proposed SparseFlex representation, TripoSF supports arbitrary-topology 3D generation and reconstruction by combining sparse voxel efficiency with flexible mesh-based geometry modeling.

2025
TPAMI

February 10, 2025

TripoSG: High-Fidelity 3D Shape Synthesis using Large-Scale Rectified Flow Models

Yangguang Li, Zi-Xin Zou, Zexiang Liu, Dehu Wang, Yuan Liang, Zhipeng Yu, Xingchao Liu, Yuan-Chen Guo, Ding Liang, Wanli Ouyang, Yan-Pei Cao

Leveraging large-scale rectified flow transformers and a curated 3D dataset pipeline, TripoSG achieves high-fidelity image-to-3D shape synthesis with strong geometric detail and cross-domain generalization.

2025
ICCV 2025

February 10, 2025

NeuFrameQ: Neural Frame Fields for Scalable and Generalizable Anisotropic Quadrangulation

Ying-Tian Liu, Jiajun Li, Yu-Tao Liu, Xin Yu, Yuan-Chen Guo, Yan-Pei Cao, Ding Liang, Ariel Shamir, Song-Hai Zhang

NeuFrameQ proposes a neural frame field representation for anisotropic quadrangulation, enabling scalable and generalizable quad mesh generation across complex 3D geometries with improved directional consistency and topology quality.

2025
CVPR 2025

December 19, 2024

DI-PCG: Diffusion-based Efficient Inverse Procedural Content Generation for High-quality 3D Asset Creation

Wang Zhao, Yan-Pei Cao, Jiale Xu, Yuejiang Dong, Ying Shan

DI-PCG builds a diffusion-driven procedural content generation framework that synthesizes large-scale, controllable 3D scenes by jointly modeling semantic layouts and geometric details for interactive virtual environments.

2024
Dec 2024

December 16, 2024

Deformable Radial Kernel Splatting

Yi-Hua Huang, Ming-Xian Lin, Yang-Tian Sun, Ziyi Yang, Xiaoyang Lyu, Yan-Pei Cao, Xiaojuan Qi

Deformable Radial Kernel Splatting replaces fixed Gaussian primitives with deformable radial kernels, improving geometric flexibility and rendering fidelity for high-quality neural surface reconstruction and view synthesis.

2024
ICCV 2025

December 4, 2024

MV-Adapter: Efficient and Versatile Adapter for Multi-view Consistent Image Generation Made Easy

Zehuan Huang, Yuan-Chen Guo, Haoran Wang, Ran Yi, Lizhuang Ma, Yan-Pei Cao, Lu Sheng

By attaching a lightweight adaptation module to pretrained diffusion models, MV-Adapter enables view-consistent multi-image generation for downstream 3D creation tasks.

2024
CVPR 2025

December 4, 2024

MIDI: Multi-Instance Diffusion for Single Image to 3D Scene Generation

Zehuan Huang, Yuan-Chen Guo, Xingqiao An, Yunhan Yang, Yangguang Li, Zi-Xin Zou, Ding Liang, Xihui Liu, Yan-Pei Cao, Lu Sheng

MIDI-3D formulates multi-instance image-to-3D generation as a diffusion process, enabling coherent reconstruction of complex scenes with multiple interacting objects from a single image input.

2024
ECCV 2024

November 27, 2024

DMiT: Deformable Mipmapped Tri-Plane Representation for Dynamic Scenes

Jing-Wen Yang, Jia-Mu Sun, Yong-Liang Yang, Jie Yang, Ying Shan, Yan-Pei Cao , Lin Gao

Rather than relying on explicit 3D supervision, WonderWorld generates immersive and explorable 3D scenes from a single image by combining panoramic scene expansion with geometry-aware multi-view synthesis.

2024
ICCV 2025

November 26, 2024

SuperMat: Physically Consistent PBR Material Estimation at Interactive Rates

Yijia Hong, Yuan-Chen Guo, Ran Yi, Yulong Chen, Yan-Pei Cao, Lizhuang Ma

A physics-guided motion generation framework that enhances human-object interaction realism by embedding physical constraints and dynamics into diffusion-based 3D motion synthesis.

2024
3DV 2026

November 25, 2024

DetailGen3D: Generative 3D Geometry Enhancement via Data-Dependent Flow

Ken Deng, Yuan-Chen Guo, Jingxiang Sun, Zi-Xin Zou, Yangguang Li, Xin Cai, Yan-Pei Cao, Yebin Liu, Ding Liang

DetailGen3D enhances coarse 3D generation pipelines with a detail-aware refinement framework, producing high-fidelity geometry and texture details while preserving the structural consistency of the original assets.

2024
SIGGRAPH Asia 2024

November 22, 2024

TEXGen: a Generative Diffusion Model for Mesh Textures

Xin Yu, Ze Yuan, Yuan-Chen Guo, Ying-Tian Liu, JianHui Liu, Yangguang Li, Yan-Pei Cao, Ding Liang, Xiaojuan Qi

TEXGen adopts a controllable texture generation pipeline that synthesizes high-resolution and style-consistent 3D textures from text prompts while preserving geometric alignment across views.

2024
TPAMI

October 16, 2024

DreamCraft3D++: Efficient Hierarchical 3D Generation with Multi-Plane Reconstruction Model

Jingxiang Sun, Cheng Peng, Ruizhi Shao, Yuan-Chen Guo, Xiaochen Zhao, Yangguang Li, Yanpei Cao, Bo Zhang, Yebin Liu

DreamCraft3D++ improves text-to-3D generation by combining hierarchical 3D Gaussian splatting with diffusion priors, enabling detailed geometry synthesis and high-quality texture refinement under complex prompts.

2024
CVPR 2025

September 16, 2024

PSHuman: Photorealistic Single-image 3D Human Reconstruction using Cross-Scale Multiview Diffusion and Explicit Remeshing

Peng Li, Wangguandong Zheng, Yuan Liu, Tao Yu, Yangguang Li, Xingqun Qi, Xiaowei Chi, Siyu Xia, Yan-Pei Cao, Wei Xue, Wenhan Luo, Yike Guo

Personalized human reconstruction from sparse-view images is achieved through PSHuman, which combines diffusion priors with geometry-aware modeling to recover detailed appearance and identity-consistent 3D humans.

2024
SGP 2025

August 27, 2024

OctFusion: Octree-based Diffusion Models for 3D Shape Generation

Bojun Xiong, Si-Tong Wei, Xin-Yang Zheng, Yan-Pei Cao, Zhouhui Lian, Peng-Shuai Wang

Built on octree-based sparse representations, OctFusion accelerates high-resolution 3D shape generation while maintaining geometric fidelity and memory efficiency in diffusion-based modeling.

2024
NeurIPS 2024

June 19, 2024

Splatter a Video: Video Gaussian Representation for Versatile Processing

Yang-Tian Sun, Yi-Hua Huang, Lin Ma, Xiaoyang Lyu, Yan-Pei Cao, Xiaojuan Qi

Splatter-A-Video brings 3D Gaussian splatting into video generation, enabling temporally coherent and spatially consistent scene synthesis from dynamic video inputs.

2024
ECCV 2024

May 19, 2024

GVGEN: Text-to-3D Generation with Volumetric Representation

Xianglong He, Junyi Chen, Sida Peng, Di Huang, Yangguang Li, Xiaoshui Huang, Chun Yuan, Wanli Ouyang, Tong He

GVGEN explores geometry-aware video generation by jointly modeling scene structure and motion dynamics, producing view-consistent videos with improved spatial coherence across frames.

2024
CVPR 2024

April 21, 2024

PI3D: Efficient Text-to-3D Generation with Pseudo-Image Diffusion

Ying-Tian Liu, Yuan-Chen Guo, Guan Luo, Heyi Sun, Wei Yin, Song-Hai Zhang

A coarse-to-fine 3D generation framework that reconstructs detailed and view-consistent geometry from sparse observations through progressive shape refinement and multi-view diffusion guidance.

2024
CVMJ 2024

March 17, 2024

Recent Advances in 3D Gaussian Splatting

Tong Wu, Yu-Jie Yuan, Ling-Xiao Zhang, Jie Yang, Yan-Pei Cao, Ling-Qi Yan, Lin Gao

High-quality 3D content generation is achieved through TripoSR, a fast single-image reconstruction approach that combines sparse volumetric representations with scalable neural rendering for efficient shape recovery.

2024
Mar 2024

March 4, 2024

TripoSR: Fast 3D Object Reconstruction from a Single Image

Dmitry Tochilkin, David Pankratz, Zexiang Liu, Zixuan Huang, Adam Letts, Yangguang Li, Ding Liang, Christian Laforte, Varun Jampani, Yan-Pei Cao

TripoSR delivers real-time single-image-to-3D reconstruction through a feed-forward framework that recovers detailed geometry and appearance with scalable sparse representations.

2024
SIGGRAPH 2024

February 27, 2024

CharacterGen: Efficient 3D Character Generation from Single Images with Multi-View Pose Canonicalization

Hao-Yang Peng, Jia-Peng Zhang, Meng-Hao Guo, Yan-Pei Cao, Shi-Min Hu

CharacterGen presents a controllable 3D character creation pipeline that generates stylized and animation-ready characters from text and image conditions with consistent geometry and appearance.

2024
ICLR 2024

January 16, 2024

Text-to-3D with Classifier Score Distillation

Xin Yu, Yuan-Chen Guo, Yangguang Li, Ding Liang, Song-Hai Zhang, Xiaojuan Qi

This work introduces classifier score distillation for text-to-3D generation, showing that classifier-free guidance can serve as the main optimization signal for high-quality 3D generation.

2024
CVPR 2024

December 14, 2023

Triplane Meets Gaussian Splatting: Fast and Generalizable Single-View 3D Reconstruction with Transformers

Zi-Xin Zou, Zhipeng Yu, Yuan-Chen Guo, Yangguang Li, Ding Liang, Yan-Pei Cao, Song-Hai Zhang

TriplaneGaussian integrates triplane representations with 3D Gaussian splatting to improve rendering efficiency and geometric quality for large-scale neural scene reconstruction and novel view synthesis.

2023
CVPR 2024

December 14, 2023

PI3D: Efficient Text-to-3D Generation with Pseudo-Image Diffusion

Ying-Tian Liu, Yuan-Chen Guo, Guan Luo, Heyi Sun, Wei Yin, Song-Hai Zhang

Progressive multi-view refinement and diffusion guidance are combined in this work to reconstruct detailed, view-consistent 3D geometry from sparse visual observations.

2023
ECCV 2024

December 13, 2023

UniDream: Unifying Diffusion Priors for Relightable Text-to-3D Generation

Zexiang Liu, Yangguang Li, Youtian Lin, Xin Yu, Sida Peng, Yan-Pei Cao, Xiaojuan Qi, Xiaoshui Huang, Ding Liang, Wanli Ouyang

A unified motion synthesis framework for generating realistic human interactions by modeling fine-grained body dynamics and temporal coherence under diverse action conditions.

2023
CVPR 2024

December 10, 2023

EpiDiff: Enhancing Multi-View Synthesis via Localized Epipolar-Constrained Diffusion

Zehuan Huang, Hao Wen, Junting Dong, Yaohui Wang, Yangguang Li, Xinyuan Chen, Yan-Pei Cao, Ding Liang, Yu Qiao, Bo Dai, Lu Sheng

EpiDiff leverages epipolar constraints within diffusion models to produce geometrically consistent multi-view image generation for downstream 3D reconstruction and scene synthesis tasks.

2023
CVPR 2024

December 5, 2023

DreamComposer: Controllable 3D Object Generation via Multi-View Conditions

Yunhan Yang, Yukun Huang, Xiaoyang Wu, Yuan-Chen Guo, Song-Hai Zhang, Hengshuang Zhao, Tong He, Xihui Liu

DreamComposer enables compositional 3D scene generation by coordinating multiple objects and semantic relationships within a unified diffusion-based creation pipeline.

2023
CVPR 2024

December 4, 2023

SC-GS: Sparse-Controlled Gaussian Splatting for Editable Dynamic Scenes

Yi-Hua Huang, Yang-Tian Sun, Ziyi Yang, Xiaoyang Lyu, Yan-Pei Cao, Xiaojuan Qi

Structured and controllable neural scene reconstruction is achieved in SC-GS through semantic-constrained Gaussian splatting, improving scene editing flexibility while preserving rendering quality and spatial consistency.

2023
CVPR 2024 · Highlight

October 23, 2023

Wonder3D: Single Image to 3D using Cross-Domain Diffusion

Xiaoxiao Long, Yuan-Chen Guo, Cheng Lin, Yuan Liu, Zhiyang Dou, Lingjie Liu, Yuexin Ma, Song-Hai Zhang, Marc Habermann, Christian Theobalt, Wenping Wang

Wonder3D generates consistent multi-view normal maps and color images from a single input image, then fuses them into a high-quality textured 3D mesh.

2023
ECCV 2024

October 9, 2023

HiFi-123: Towards High-fidelity One Image to 3D Content Generation

Wangbo Yu, Li Yuan, Yan-Pei Cao, Xiangjun Gao, Xiaoyu Li, Wenbo Hu, Long Quan, Ying Shan, Yonghong Tian

HiFi-123 focuses on high-fidelity single-image-to-3D generation, reconstructing detailed geometry and textures through diffusion-guided multi-view consistency optimization.

2023